

Which AI Writes the Best AutoHotkey v2? I Tested 12 of Them
I use AI to write AutoHotkey every single day. So one question kept nagging at me: which model is actually the BEST at it?
Turns out that’s a trickier question than it sounds, because “best” isn’t one thing.
Most people jump straight to “does the code work?” And yeah, that matters a TON. AutoHotkey is a niche language, it’s not splattered all over the internet like Python or JavaScript, and a lot of models love to sneak in old v1 syntax that blows up in v2. So step one is simple: does the script actually run?
But that’s not the whole story. Think about how YOU actually pick a tool. There’s more than one thing you care about:
- Does it work? Valid, clean v2 syntax that runs the first time. The big one.
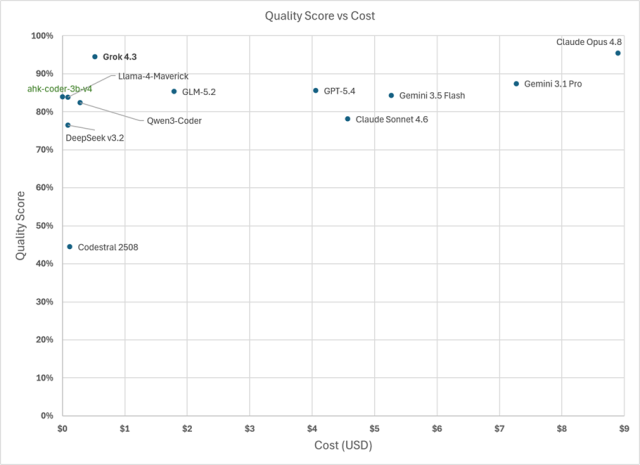
- How much does it cost? Some of these models are 10x or even 90x pricier than others. If a cheap one is “90% as good,” that’s a HUGE deal when you’re running hundreds of requests.
- How fast is it? A brilliant answer that takes 30 seconds can be worse than a good answer in two. Speed is productivity.
- What about your privacy? Every prompt you send to a cloud model leaves your machine. For a lot of my work, that’s fine. For client code or anything sensitive, running a model locally (where nothing ever leaves your computer) is worth a lot.
- Can you even run it yourself? An open model you control beats a black box you rent, at least for some jobs.
So I decided to stop guessing and actually measure it. I ran 12 models (11 of the big cloud players plus a little 3B model I trained on AutoHotkey scripts, Our AHK Courses, Our AHK Claude Skills and Agents, the AHK V2 Documentation, AHK V2 Code extension, and v2 git repositories) through the exact same set of tasks, scored the same way, and tracked what each one cost.
The results surprised me. The most EXPENSIVE model didn’t win. And my tiny home-grown model, running free on a single desktop GPU, held its own against models that cost real money. 🤖
The leaderboard
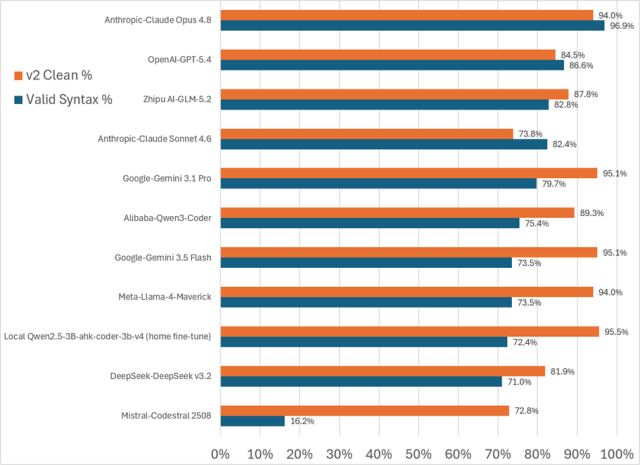
| # | Model | Maker | Valid syntax | v2-clean | Cost |
|---|---|---|---|---|---|
| 1 | Grok 4.3 | xAI | 98.5% | 90.5% | $0.52 |
| 2 | Claude Opus 4.8 | Anthropic | 96.9% | 94.0% | $8.90 |
| 3 | GPT-5.4 | OpenAI | 86.6% | 84.5% | $4.06 |
| 4 | GLM-5.2 | Zhipu AI | 82.8% | 87.8% | $1.79 |
| 5 | Claude Sonnet 4.6 | Anthropic | 82.4% | 73.8% | $4.57 |
| 6 | Gemini 3.1 Pro | 79.7% | 95.1% | $7.27 | |
| 7 | Qwen3-Coder | Alibaba | 75.4% | 89.3% | $0.28 |
| 8 | Llama-4-Maverick | Meta | 73.5% | 94.0% | $0.09 |
| 9 | Gemini 3.5 Flash | 73.5% | 95.1% | $5.27 | |
| 10 | ahk-coder-3b-v4 my home fine-tune | Local, Qwen2.5-3B | 72.4% | 95.5% | $0.00 |
| 11 | DeepSeek v3.2 | DeepSeek | 71.0% | 81.9% | $0.09 |
| 12 | Codestral 2508 | Mistral | 16.2% | 72.8% | $0.12 |
Cost is the total I spent to run each model across the task set (the home model is free to run). Models are ranked by the share of answers that parsed as valid AutoHotkey v2.
Code Quality
Quality vs Price
The tests I ran
Every model got the same 150 tasks. And here’s the important part: those tasks came from a hold-out set my fine-tuned model never saw while training. So nobody gets an “I memorized this” advantage. The tasks come in three flavors, the same way I actually use AI for AutoHotkey:
| Task | # | What the model has to do |
|---|---|---|
| Write | 54 | Build a complete AHK v2 script from a plain-English description. |
| Explain | 66 | Read a script and explain, step by step, what it does. (Tests understanding, not code.) |
| Refactor | 30 | Take a script and clean it up: fix v1 patterns, modernize to good v2. |
The 84 tasks that expect code (Write plus Refactor) are the ones I ran through the syntax checker. The 66 Explain tasks are prose, so they don’t get syntax-scored. English isn’t AutoHotkey. 😊
Every answer went through the same pipeline:
- Pull out the code from the reply, so a model gets judged on its code, not on how chatty it is.
- Check the syntax by running the script through the real AutoHotkey v2 parser. It either parses or it doesn’t.
- Scan for v1 leaks, the old patterns (like
MsgBox,or%var%) that shouldn’t show up in v2. - Separate real fails from blips, if a model returned nothing because of a network hiccup, that doesn’t count against its score.
What surprised me
- Grok 4.3 is the value king. Best syntax score AND the cheapest of the big models. It beat Opus while costing 1/17th the price. That’s wild.
- Price does NOT predict quality. The two priciest models (Opus at $8.90, Gemini Pro at $7.27) both got out-scored on syntax by a 52-cent model. Don’t assume expensive means better.
- My little home model punched way above its weight. At just 3 billion parameters it beat DeepSeek v3.2 and Codestral on syntax, and wrote the cleanest v2 code of anything I tested (the single highest v2-clean score in the whole field). Running free, on my own desktop, with nothing leaving my machine. This model is small enough that should run on most Windows computers❗
- Bigger isn’t always smarter. A focused little model that knows ONE thing beat much larger general-purpose models at that one thing. For a niche language, that’s a big lesson.
How I trained the home model
That ahk-coder-3b-v4 entry isn’t a cloud model. It’s a small open model I fine-tuned at home to do one job: write good AutoHotkey v2. Here’s the recipe:
- The starting point: Qwen2.5-Coder-3B, a small open coding model.
- The training data: 1,729 of my own hand-written AutoHotkey v2 scripts. I had a frontier model turn each one into training examples (write, explain, refactor), the same three flavors as the test.
- The cleanup: I filtered hard, tossing anything truncated, broken, v1-leaking, or duplicated, down to 947 verified-clean examples. Fixing one nasty data bug in this step is what jumped the score 22 points. The lesson: garbage in, garbage out is REAL.
- The hardware: QLoRA fine-tuning on a single NVIDIA RTX 3060 (12GB), a regular desktop card. Then I run it locally through Ollama, so inference is free and offline.
- The iterations: it took four versions (v1 to v4). Versions 1 through 3 I chased the problem by tweaking training knobs, and the score barely budged (~44%). The real win came in v4 when I stopped fiddling with settings and fixed the DATA instead. (I also tried a 7B version, it wouldn’t fit on the 3060 for training. And a focused 3B beat the stock 7B anyway.)
So what’s the takeaway? There’s no single “best.” If you want the strongest AutoHotkey coder right now and you’re paying per call, Grok 4.3 is a no-brainer on both quality and price.
But if privacy or cost-at-scale matters, a small model trained on YOUR code can get you most of the way there for free.
The bigger lesson, though? Stop guessing and start measuring. I almost just assumed the expensive model was best. Testing it took an afternoon and completely changed which model I reach for.
How about you? Which model have you been leaning on for your AutoHotkey work? 🚀
